Playground

Test it on your own documents.

Everything below is live in the playground today. Run your own files through it, look at the JSON it returns, and judge the accuracy yourself — on your formats rather than on a demo set.
15
Live capabilities
JSON
Every response
366M
Parameters
No signup
To try it
wide image
It is not a chatbot

REX42 is a working component, not a conversation.

It is not competing with ChatGPT or Claude and it is not trying to be an assistant. You pass data in through an API and it replies in JSON — simple, lightweight, and small enough to embed inside a device.

What it is not
An open-ended assistant
No personality, no long-form essays, no general world knowledge, no browsing. If that is what the job needs, a large hosted model is the right tool and we will tell you so.
What it is
A machine-readable workforce
One defined task, one structured answer, returned fast enough to sit inside a real workflow — and honest enough to say when it could not read something.
POST /v1/extract
{
  "task": "emirates_id",
  "file": "base64:iVBORw0KGgoAAAANSUhEUg..."
}
200 OK — application/json
{
  "name": "Ahmed Al Mansoori",
  "id_number": "784-1987-1234567-1",
  "nationality": "United Arab Emirates",
  "expiry": "2029-03-11",
  "confidence": 0.96,
  "unreadable": []
}
What the model can do today

Fifteen tasks, live in the playground.

Grouped the way you would actually use them. Each one is a separate task the model was trained for, not a prompt wrapped around a general model.

General
General chat
Short, grounded question-and-answer inside your own product.
Documents and IDs
Visiting card
Name, role, company, phone, email and address as structured fields.
Emirates ID
Holder details, ID number, nationality and expiry.
Passport
MRZ and printed fields, cross-checked against each other.
Invoice / receipt
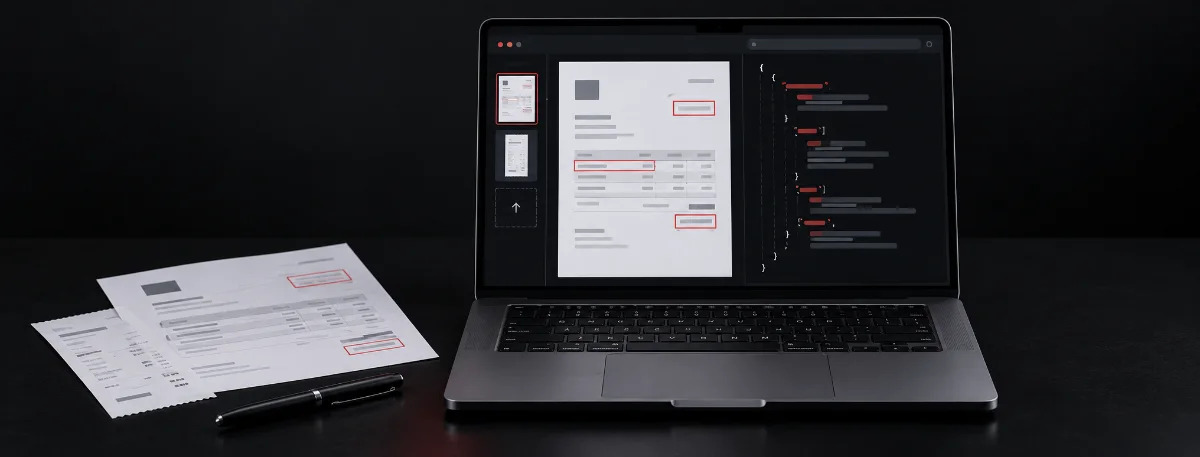
Supplier, line items, totals, VAT and dates.
CV / resume
Contact details, roles, dates, skills and education.
Tenancy contract
Parties, premises, term, rent and payment schedule.
Duplicate detection
The same customer entered three times with three spellings.
Meeting details
Attendees, decisions, dates and actions out of raw notes.
Text
Summarise
Long documents and correspondence reduced to the decisions.
Rewrite
Same meaning, different register or length.
Grammar check
Correction without rewriting the author’s voice.
Change tone
Formal, plain, firm or warm — on demand.
Sentiment and intent
Routing and prioritising against your own category list.

This list grows per client rather than per release: because we train the models ourselves, a task that matters to your business can become a capability of your model.

Live today

What you can test

n image
Documents
IDs and documents
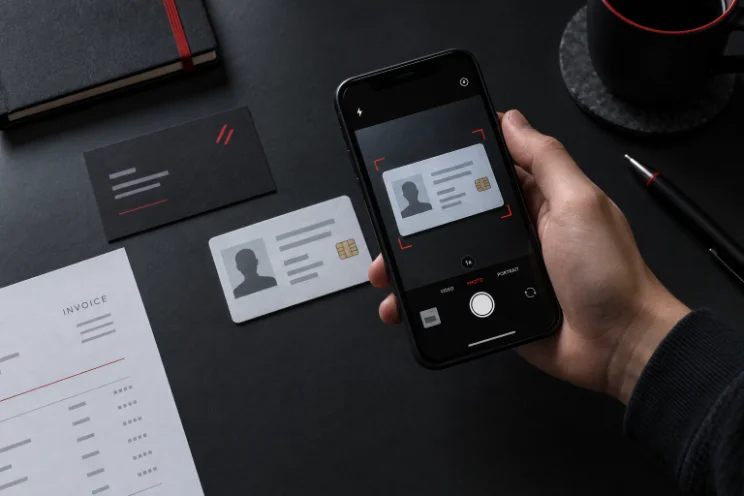
Visiting cards, Emirates IDs, passports, invoices, CVs and tenancy contracts.
n image
Text
Summarise and rewrite
Summaries, rewrites, grammar, tone, and sentiment against your own categories.
n image
Detection
Duplicates and intent
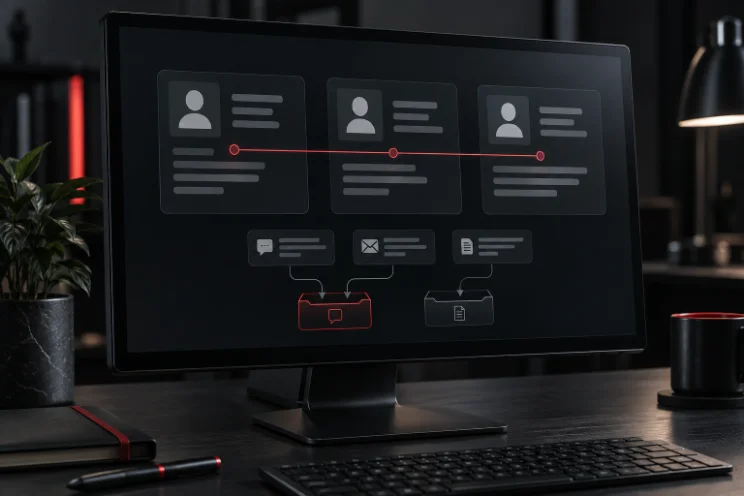
The same customer three times with three spellings, and messages routed by intent.
Small enough to live inside the device

In-device AI, not a cloud dependency.

At 4-bit the model is about 200 MB of storage and under 1 GB of RAM. That is what makes it implementable inside a smartphone, a smart device, or an industrial box on a factory floor — where a hosted model simply cannot go.

Inside a smartphone
Capture and read a document on the handset. Nothing is uploaded, and it works with the aeroplane mode switch on.
Inside a smart device
Kiosks, scanners and point-of-sale terminals that need to understand a document without a connection to anywhere.
Inside your product
Ship it as a component of your own software — one HTTP endpoint, structured output, no third-party API in your dependency tree.

The interface is identical wherever it runs. A workflow built against a server deployment moves to an on-device deployment without a rewrite.

In-device AI

Small enough to live inside the device.

About 200 MB of storage and under 1 GB of RAM at 4-bit. That is what makes it implementable inside a smartphone, a kiosk, or an industrial box — and the interface is identical wherever it runs.
n image
How to test it properly

Use your worst documents, not your best ones.

STEP 1
Pick one real task
Choose a workflow you actually run daily — invoices, IDs, CVs — rather than a broad trial.
STEP 2
Use messy inputs
Photographs at an angle, scans with stamps over text, mixed English and Arabic. That is where accuracy is decided.
STEP 3
Read the JSON
Check the fields, the confidence value and what landed in unreadable. A blank field is a correct answer.
STEP 4
Then talk to us
A model fine-tuned on your archive performs materially better than the general playground build. That is the actual product.

Run your own documents through it.

The playground is open. If the general model gets close, a model trained on your archive will get closer.